
Meta researchers build AI that learns equally well from visual, written and spoken material
Self-supervised learning, where machines learn by directly observing their environment rather than being explicitly taught with labeled images, text, audio and other data sources, has become the foundation of many significant recent advances in AI.
But while people seem to learn in the same way regardless of how they take in information, whether they use sight or hearing, for example, there are currently big differences in how self-supervised learning algorithms learn from images, speech, text and other data.
This mismatch has been a serious obstacle to wider application of advances in self-supervised learning. Because a powerful algorithm designed, say, to understand images cannot be directly applied to another modality, such as text, it is hard to advance several modalities at the same pace.
That is why Meta AI developed data2vec, the first high-performance self-supervised algorithm that works for multiple modalities. Data2vec was applied separately to speech, images and text, and it outperformed previous best single-purpose algorithms for computer vision and speech, and is competitive in NLP (natural language processing) tasks.
This represents a new paradigm of holistic self-supervised learning, where new research improves multiple modalities rather than just one. It also does not rely on contrastive learning or reconstruction of the input example.
Data2vec not only helps speed progress in artificial intelligence, but also brings us closer to building machines that seamlessly learn different aspects of the surrounding world. This will enable more adaptable AI that, researchers believe, could perform tasks beyond the capabilities of today's systems.
How data2vec works
Much of AI still relies on supervised learning, which works exclusively with labeled data. But it is simply impossible to collect labeled data on all the things we would like machines to do. For example, although researchers have done a lot of work creating large-scale labeled datasets for English speech and text, this is impossible for literally thousands of languages spoken on the planet.
Self-supervision allows computers to learn about the world simply by observing it, and then figuring out the structure of images, speech or text. Having machines that do not need to be explicitly taught to classify images or understand spoken language is far more scalable.
Today's research on self-supervised learning almost always focuses on one specific modality. As a result, researchers working on one modality often use a completely different approach than those working on another. As for text, researchers train models to fill in gaps in sentences.

Speech models, however, must learn a list of basic sounds of speech in order to predict missing sounds. In computer vision, models are often trained to assign similar representations to a color image of a cow and the same image flipped upside down, so they link them much more closely than to an unrelated image, such as a picture of a duck.
Algorithms also predict different units for each modality: pixels or visual tokens for images, words for text, and learned sets of sounds for speech. A set of pixels differs greatly from a sound wave or a passage of text, so developing an algorithm is tied to a specific modality. This means algorithms still work differently in each modality.
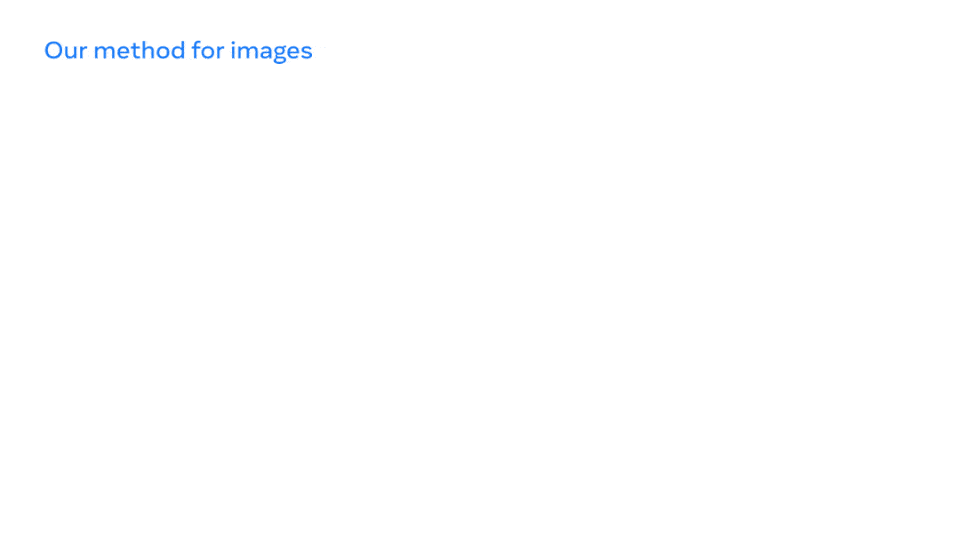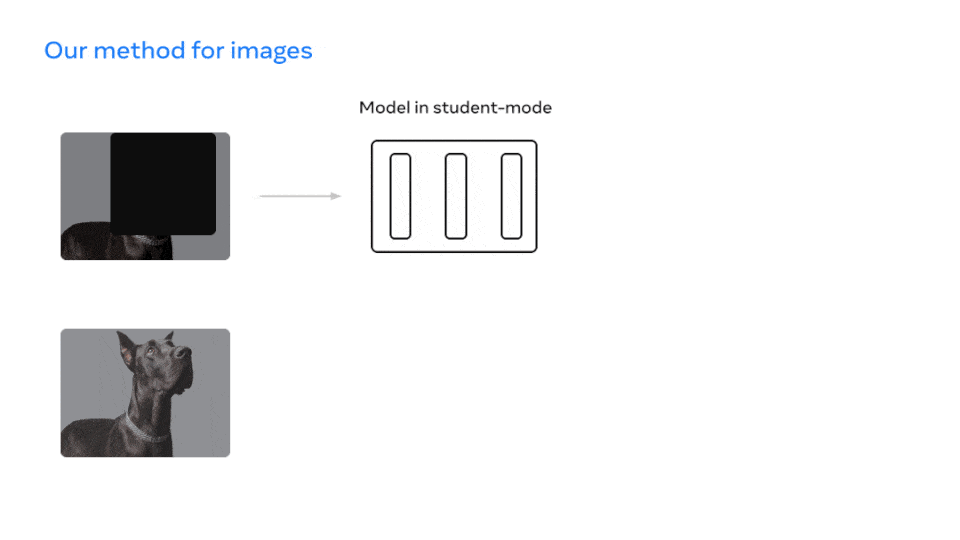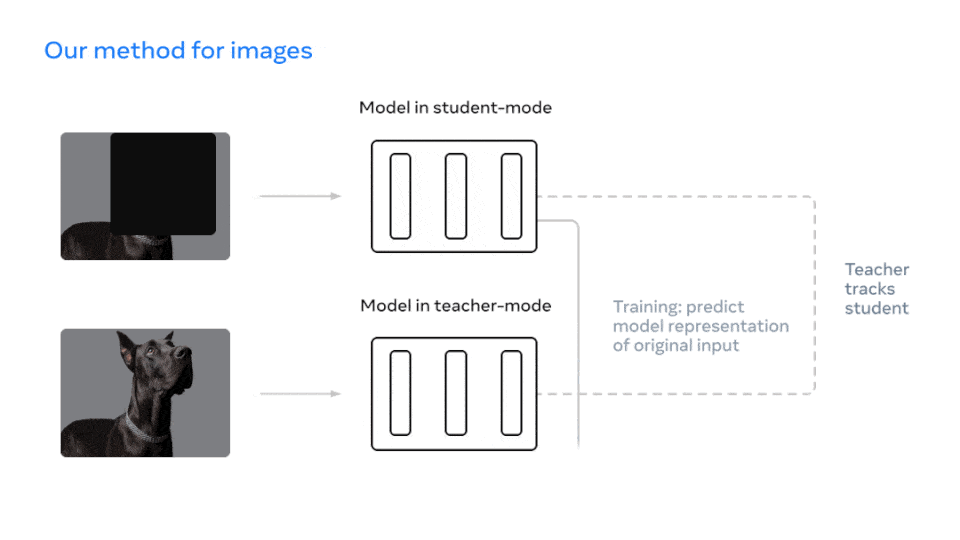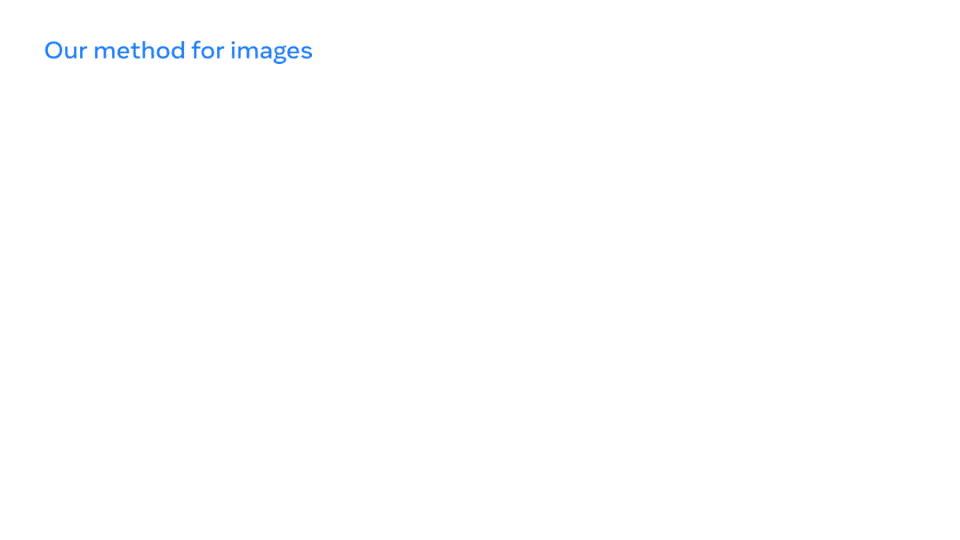
Data2vec simplifies this by training models to predict their own representations of input data, regardless of modality. By focusing on these representations, which are layers of a neural network, rather than predicting visual symbols, words or sounds, one algorithm can work with very different types of input data.
Meta researchers' method uses a teacher network to first compute target representations from an image, a text fragment or a speech utterance. Then part of the input is masked and the process is repeated with a student network, which then predicts the teacher's hidden representations. The student model must predict the representation of all the input data, even though it has a representation of only part of the information.
The scientists tested this method on the popular ImageNet computer vision benchmark, where it performed better than existing methods for popular model sizes. For speech, they found it works better than wav2vec 2.0 or HuBERT, two previous Meta AI self-supervised speech algorithms. For text, they tested it on the popular GLUE benchmark, and it showed the same results as RoBERTa, a reimplementation of BERT.

While self-supervised learning has achieved great success in computer vision, video and other individual modalities using various training objectives, the core idea of this approach is more general learning: AI should be able to learn to perform many different tasks, including completely unfamiliar ones.
Researchers want a machine to not only recognize animals shown in training data, but also adapt to recognizing new creatures if it is told what they look like. Data2vec demonstrates that the same self-supervised algorithm can work well across different modalities, and often better than the best existing algorithms.
This paves the way toward more general self-supervised learning and brings us closer to a world in which AI can use videos, articles and audio recordings to learn complex things, such as playing soccer or various ways of baking bread. The company hopes data2vec will bring us all closer to a world in which computers need very little labeled data to perform tasks.
Because it is difficult, and sometimes impossible, to collect annotated examples, for example for training speech recognition models for thousands of languages, data2vec is an important step toward more general AI.
“People understand the world through a combination of sight, sound and words, and similar systems will one day be able to understand the world just as we do”
This is still an early stage of research, so do not expect the legendary "general AI" to appear suddenly, but an AI with a generalized learning structure that works across different domains and data types seems a better and more elegant solution than the patchwork of micro-intelligences we make do with today.


